How AI parses a job description: The Mechanics, Explained
A parser first breaks a JD into sections it can reason about separately: company overview, responsibilities, requirements, compensation. JDs without clear headers force the model to guess at boundaries, and that's usually where accuracy starts slipping.
Inside each section, the parser pulls out discrete fields like skills, certifications, and experience thresholds, and has to resolve ambiguity that a rule-based system couldn't, like reading "5+ years building distributed systems" as one requirement, not two.
Separating must-haves from nice-to-haves is the step that decides whether the output is actually usable. Parsers weigh this by position, repetition, and explicit language like "required" versus "a plus."
The same requirement can extract cleanly and still misread the role. A builder-versus-maintainer distinction with identical tools and years of experience doesn't survive extraction unless the parser is built to catch it.
Extracted fields get normalized against a standard taxonomy, so "GCP" and "Google Cloud Platform" count as the same skill, and seniority becomes comparable across companies.
Vendor accuracy numbers are usually measured against clean, well-structured JDs. The same parser run against a narrative-style or template-recycled posting performs worse.
Salary transparency laws, now active in 16 U.S. states plus D.C., mean parsers increasingly need to pull compensation out as a structured field, not free text.
Most articles on AI JD parsing tell you what it does. Almost none explain what's actually happening when a parser reads a job description, or where that process breaks.
If an AI parser has ever confidently mislabeled a nice-to-have as a hard requirement, or missed a salary band that was sitting right there in the text, this is why.
What does JD parsing mean?
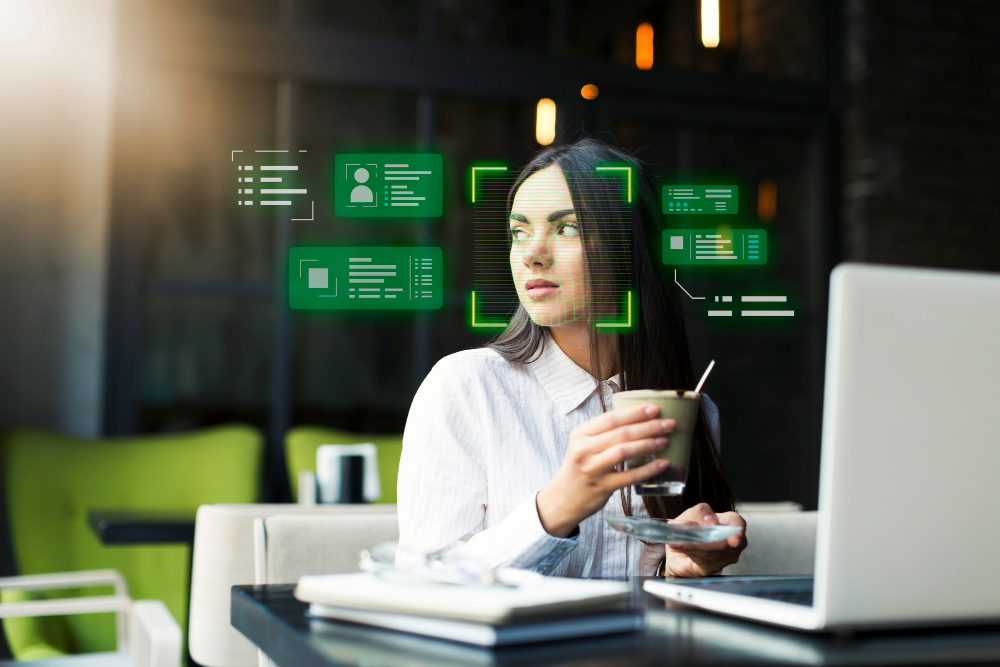
JD parsing turns a job description into structured, queryable fields: job title, responsibilities, required skills, experience level, location, compensation. An AI parser does this with NLP and LLMs instead of manual tagging. It reads unstructured text written for a person and hands back data a system can act on.
That's the short version. The mechanics underneath it are where most guides stop, so that's where this one starts.
How an AI JD parser actually works
Step 1: Segmentation
The parser breaks the raw text into sections it can reason about on their own: company overview, role summary, responsibilities, requirements, compensation, benefits. A well-structured JD with clear headers makes this easy. A JD with no headers, or one that buries the requirements inside a narrative paragraph, forces the model to guess at boundaries. That's usually where accuracy starts to slip.
Step 2: Field extraction and classification
Inside each section, the parser pulls out discrete data points and labels them: a skill, a certification, a years-of-experience threshold, a tool name. This is where LLMs beat older rule-based parsers, because they have to resolve ambiguity. "5+ years building distributed systems" needs to read as one experience requirement tied to one skill, not two unrelated facts.
Soft skills get pulled out the same way when they're stated directly, communication, leadership, ownership, though a parser has less to anchor them to. A tool name or a certification is either present or it isn't. "Strong communication skills" is present in almost every JD, which makes it a weak signal no matter how confidently a parser extracts it.
Step 3: Context and intent mapping
Some of what a JD asks for never shows up as a discrete skill or requirement. "Fast-paced environment" doesn't name a tool or a certification, but it's still signaling something: high change velocity, less structure, maybe longer hours than the rest of the posting lets on. A parser working only off literal field extraction misses this entirely, because there's no field for it to fill.
An LLM-based parser can read past the surface language and infer what a phrase like this is actually implying, closer to how a person reading the posting would. This step doesn't produce a hard requirement the way a skill or an experience threshold does. It produces a softer signal, one that matters more to a candidate deciding whether to apply than to a scoring model deciding how to rank a resume.
Step 4: Must-have vs. nice-to-have separation
This step decides whether the output is actually useful. A raw requirements list mixes non-negotiable criteria with wish-list items. Treat them the same, and the scoring model built on top of it gets too loose to trust. A good parser weighs this by position (what's listed first), repetition (mentioned more than once), and explicit language ("required" versus "preferred" versus "a plus").
Which is also why writing must-haves specific enough to actually screen against matters as much on the writing side as it does on the parsing side.
This step also produces some of the worst downstream errors. Take a JD asking for a builder, someone standing up new infrastructure from scratch. Parse it naively, and a maintainer profile, someone who keeps existing systems running, can score just as well; same tools, same years of experience. The words match. The distinction between building and maintaining doesn't survive extraction unless the parser is built to catch it.
Step 5: Normalization
Extracted fields get mapped to a standard taxonomy, so "GCP," "Google Cloud," and "Google Cloud Platform" count as the same skill, and a Senior Software Engineer at one company can be compared on seniority to a Staff Engineer at another. That mapping is a deep topic on its own, and how skills taxonomy connects to JD parsing is worth reading if you want the full picture.
Where JD parsing still breaks in 2026?
Most content on this topic stops at the benefits. Here's what still goes wrong.
Ambiguous or missing structure is still the most common failure. A JD with no section headers, written as one narrative block, forces the parser to guess at boundaries, and each guess compounds into the next.
A parser can also extract every field correctly and still misread the role. Builder versus maintainer, IC versus lead-track, generalist versus specialist: identical tooling and years of experience, genuinely different jobs. Nothing in the extraction was wrong. The output still misrepresents the role.
Legacy ATS integration is a real project, not a checkbox. Older systems weren't built around structured JD data, and mapping a parser's output cleanly into existing fields, especially with years of inconsistent historical postings sitting in the database, takes real work.
Data privacy matters more than most guides mention. JDs sometimes carry sensitive internal detail: reporting lines, unannounced initiatives, compensation bands that were never meant to go public. Any parser touching that data needs real controls on storage and access.
And the accuracy numbers vendors quote need context. A 95%+ accuracy claim is usually measured against clean, well-structured JDs. Run the same parser against a JD that's been copy-pasted from an old template three times, missing half its sections, and accuracy drops. Ask what kind of input was tested before you trust the number.
What changed in 2026
Two shifts are reshaping what a parser needs to handle.
Salary transparency laws are now active in 16 U.S. states plus Washington, D.C. Parsers need to pull compensation out as a structured field, not free text, and flag postings where the range is missing or vague.
Years-of-experience requirements are disappearing. Skills-based hiring has pushed them out of many postings, down to roughly 30% of U.S. job listings from around 40% a few years back. That means parsers increasingly have to infer seniority from how the responsibilities section is written, instead of reading it off a number. Harder problem than it was two years ago.
A practical example
Take a JD for a Senior Backend Engineer at a Series B startup. Responsibilities: own a payments infrastructure migration. Requirements: 5+ years backend experience, Python, distributed systems, and near the bottom, "AWS a plus."
A parser working through the steps above should flag payments infrastructure and distributed systems as must-haves (they show up in both sections), Python as a must-have (repeated, listed first), and AWS as a nice-to-have (explicitly qualified, listed last). That distinction is what decides whether a resume showing "3 years AWS, no payments experience" outranks one showing "6 years backend, led a payments migration, no AWS." Get the must-have split wrong, and the ranking that follows is wrong, no matter how good the matching model underneath it is.
Recrew's JD Builder runs on the same logic. It walks a hiring manager through building the JD conversationally, then extracts must-have criteria as a separate step, reading the JD in the order a recruiter actually would: company context, then role, then responsibilities, then requirements. That order is what lets the extraction reflect what actually matters most instead of just what's listed. Those must-haves then feed straight into how resumes get scored against the role, instead of sitting in a document nobody opens again.
FAQs
1. Does AI JD parsing replace writing a good job description?
No, parsing extracts what's already there. It can't invent clarity that doesn't exist. A vague or contradictory JD produces vague or contradictory parsed output, no matter how good the parser is.
2. How accurate is AI JD parsing in 2026?
Depends on the input. Well-structured JDs with clear headers and specific requirements parse reliably. Narrative-style or template-recycled JDs introduce real errors, especially around must-have versus nice-to-have classification.
3. Can a JD parser tell the difference between similar job titles?
Only if it's built to look past title and tool overlap into what the responsibilities section actually describes. Title and skill-list matching alone will conflate roles that need genuinely different experience.
4. What happens to compensation data during parsing?
A good parser extracts stated salary ranges as a structured field and flags postings where compensation is missing or vague. With salary transparency laws now active in 16+ states, that's becoming a standard requirement, not a nice-to-have feature.